Monthly reliability reporting often involves a substantial amount of preparation before the review itself can begin. Utilisation has to be checked, defect and delay data brought together, component removals reviewed and questionable records resolved. In many organisations, this information is spread across several systems, exports and locally maintained files, which means Reliability Engineering can spend a significant part of the reporting cycle preparing the data rather than reviewing fleet performance.
The workload tends to increase as the operation becomes more complex. Additional aircraft, systems and specialist workflows create more sources of operational information, even when each individual system performs its intended function well. Reliability Engineering still needs a consistent view across those sources before it can determine what is changing across the fleet and where further investigation may be required.
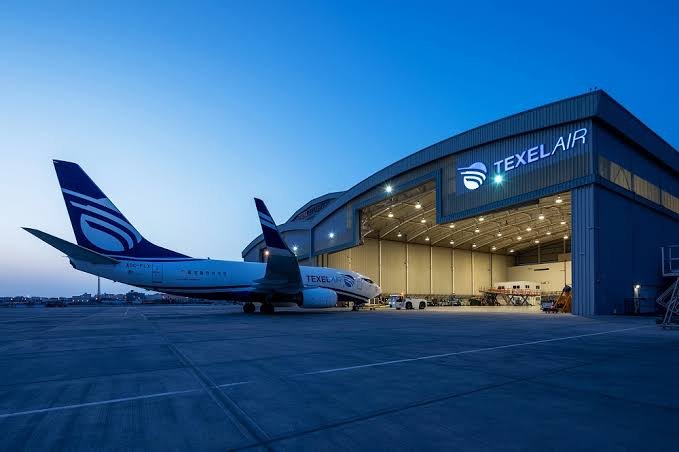
Texel Air encountered this challenge as its operation expanded. The cargo operator introduced additional systems across maintenance, electronic technical logs, flight operations and aircraft data while also supporting a second AOC. Its experience provides a useful example of how changes to data flow, validation and reporting can reduce the amount of preparation required before technical analysis begins.
The Reporting Problem Often Starts Upstream
A monthly reliability report draws on information created throughout the operation. Aircraft utilisation feeds rate-based calculations, defect records support ATA and repetitive-defect analysis, technical delays contribute to dispatch reliability, and component removals are used for measures such as MTBUR and MTBF. Maintenance findings may also be required when reviewing programme effectiveness.
These records rarely originate in one place. The M&E system remains central, but information may also come from an electronic technical log, flight operations systems, aircraft data sources and other specialist applications. By the time the monthly review begins, Reliability Engineering may already be working across several operational datasets.
For that reason, reporting efficiency cannot always be improved at the reporting stage alone. If information has already been copied, re-entered or reconciled several times before it reaches the engineer, the monthly process inherits that complexity. The amount of preparation required before the first calculation is made can therefore be as important as the speed at which the final report is generated.
For a closer look at that preparation burden, see The Hidden Work Behind Monthly Aircraft Reliability Reporting.
Reducing Repeated Handling of Operational Data
One way to reduce that workload is to look at how operational information moves between systems. Repeated data entry remains common in engineering environments, particularly where information created in one system is later copied into another application, exported into a spreadsheet, and adjusted again for reporting.
Each additional hand-off increases the amount of manual work and creates another opportunity for differences to appear between records. A more efficient approach is to keep the specialist operational systems in place while reducing unnecessary manual transfers between them. Where appropriate, information entered once can then be made available to the other workflows that depend on it.
This does not remove the need for validation, but it reduces the amount of reconciliation that has to be repeated at month-end. Relationships between flights, defects, delays, and component events can be maintained as part of the normal data flow rather than rebuilt each time the monthly report is prepared.
Subscribe to the newsletter
Practical guidance on aviation data management, delivered straight to your inbox.
Moving Data Checks Earlier in the Cycle
Data-quality issues will still occur in any operational environment. A flight record may contain an unusual duration, a sequence may be incomplete, or a defect or component event may not align with the surrounding records. These issues can appear minor when they first occur but become more significant once they feed reliability calculations.
If they are only discovered during report preparation, the engineer has to stop the analysis, trace the issue back to the source,
and correct the information before continuing. Recurring checks allow questionable records to be identified earlier and reviewed closer to the point at which they entered the process.
The timing is particularly important for utilisation data because an incorrect flight-hour or cycle record can influence several reliability indicators. The same applies to defect, delay and component information. Moving validation into the normal operating cycle reduces the amount of corrective work that accumulates at the reporting deadline and gives Reliability Engineering a more stable information base to work from.
What Changed at Texel Air
Texel Air applied this approach to an environment in which several specialist systems were already supporting the operation. One of the principles adopted during the project was that information should be entered once and then made available to the other systems that required it, reducing repeated data handling across the engineering workflow.
The airline also introduced recurring M&E consistency checks, carried out daily or weekly, to identify records that required attention. Andres Kjerulf, Director of Airworthiness at Texel Air, has described how incorrect entries previously required the team to trace issues back through the organisation before the cause could be understood.
The change became particularly visible in the reporting cycle. Texel Air reports that reliability and reporting work that previously took days can now be completed in hours. The airline has also reported less manual rework, fewer duplicated tools, reduced audit-preparation effort and more consistent information for Engineering and Safety.
These outcomes are important because the improvement was not limited to the report itself. It followed changes in how operational information moved between systems and how data issues were identified before the monthly review began.
From the KPI Into the Investigation
Once the report is available, Reliability Engineering still has to determine what sits behind the figures. A rise in defects may require a closer look at particular aircraft or ATA chapters, while a deterioration in component performance may lead to part numbers, removal reasons or individual events. Changes in technical dispatch reliability may also be driven by a relatively small number of recurring delay causes.
Where the KPI and the underlying records are separated, further analysis can quickly turn into another data-preparation exercise. Engineers may have to create new exports or spreadsheets simply to understand which records contributed to the result. Keeping the reporting output closer to the operational data allows the investigation to continue without repeatedly rebuilding the same information.
The engineering judgement remains unchanged. The purpose of the analytical environment is to make the relevant records easier to reach so that the engineer can determine whether the change is technically significant and whether further action is required.
Our article Following the Reliability Signal: From Fleet KPI to Technical Investigation looks at that process in more detail.
Component Reliability as an Example
Component reliability illustrates this requirement particularly well. Measures such as MTBUR, MTBF and unscheduled removal rate can show that performance is changing, but the aggregate figure provides limited technical context on its own.
Engineering still needs to establish which components are involved, which aircraft they came from, whether removal reasons show a pattern and whether the behaviour is isolated or recurring. If that information has to be assembled separately every time an indicator changes, the analysis remains disconnected from the reporting process.
Texel Air has applied this approach within its own component reliability work, where Engineering can review the records behind the overall result and create follow-up tasks where further investigation is required. This allows the team to move more directly from a fleet-level measure into the component population and operational events contributing to it.
Reliability Analysis Has to Reflect the Operation
Fleet-wide indicators provide an important overview, but reliability work often becomes more specific as soon as a trend requires attention. The review may move from the fleet to an individual aircraft, an ATA chapter, a component population or a particular operating requirement.
Texel Air, for example, operates both EDTO and non-EDTO aircraft and has developed dedicated EDTO views covering relevant ATA chapters, components and tasks, together with engine and APU condition information and oil-consumption monitoring.
The requirement is broader than the EDTO example. Reliability teams regularly need to change the level at which they review the same operational information. A useful analytical environment therefore needs to support those changes in perspective without requiring the engineer to recreate the analysis from the beginning each time.
From Reliability Reporting to Reliability Intelligence
The workflow extends beyond monthly reporting. Operational records first have to move between systems with as little unnecessary handling as possible. Questionable data needs to be identified before it becomes a month-end problem, and recurring reporting needs to be consistent enough for changes between periods to be meaningful. Once an indicator moves, engineers then need access to the operational detail required for further investigation.
At EXSYN, this combination of data validation, reliability reporting and engineering analysis is described as Reliability Intelligence. The M&E system continues to hold the controlled maintenance record, while EXSYN works alongside it to support the data checks, recurring calculations and analytical views used by Reliability Engineering.
The aim is to reduce the amount of effort spent preparing the reliability picture and make the transition from reporting into investigation more direct, while leaving technical assessment and engineering action with the airline's Reliability and Airworthiness teams.
For a closer look at what happens after the data preparation stage, explore our aircraft reliability reporting workflow, from monthly reliability indicators to fleet-level analysis and technical investigation.
What Other Reliability Teams Can Take From the Example
The circumstances at Texel Air are specific to its fleet and operation, but the underlying challenge is common. Most airlines already hold the data required for reliability work; the difficulty lies in how much effort is required to bring that information together, validate it, and then understand what the resulting indicators are showing.
For teams reviewing their own process, it is useful to consider how much of the monthly cycle is spent preparing information before the review, when data-quality issues are normally detected and how easily an engineer can move from a changing KPI into the aircraft, defect or component behind it.
Texel Air's reduction in reporting time from days to hours provides a practical indication of what can change when those parts of the workflow are addressed together. The broader improvement is visible in the reduction of repeated data handling, earlier identification of questionable records and a more direct route from the monthly report into engineering analysis.
The Operator's View
Texel Air has described the wider project directly in Aircraft IT MRO. In From Data Silos to Insight, Andres Kjerulf covers the airline's original data challenges, system integration, recurring data checks, defect and component analysis, EDTO oversight, and the operational changes achieved during the project.
For reliability and engineering teams considering a similar approach, the article provides the operator's perspective on both the technical implementation and the internal processes around data ownership and follow-up.